
A team at Multiverse Computing says it has built a smaller, faster variant of China’s DeepSeek R1 and removed its political guardrails. The company calls it DeepSeek R1 Slim and claims it is roughly half the size of the original while keeping reasoning quality comparable. The public pitch centers on an “uncensored, 55%-compressed” R1 made available through an API and the AWS Marketplace, with the savings credited to a quantum-inspired compression method named CompactifAI. Multiverse Computing provides technical documentation detailing the model’s size reduction and uncensored capabilities.
The idea of “de-censoring” a Chinese foundation model is controversial. Prior reporting has shown that DeepSeek’s default behavior suppresses or redirects politically sensitive questions, with controls present both in application layers and in the trained model itself, as documented by independent testing. Multiverse argues that compression presents researchers a clearer map of the model’s internal correlations, which can then be edited before a final fine-tune to keep behavior close to baseline performance. MIT Technology Review summarized the news and reported that the slimmed model answered previously blocked prompts.
The implications extend far beyond geopolitics. Packing a high-quality reasoner into a smaller model enables more organizations to run it on cheaper hardware with lower power draw. This shift carries major sustainability implications as electricity demand from data centers rises quickly; the International Energy Agency projects global consumption by data centers could reach about 945 terawatt-hours by 2030. The rest of this article explains what actually changed inside R1 Slim, how the method works, and when smaller models truly translate into greener AI.
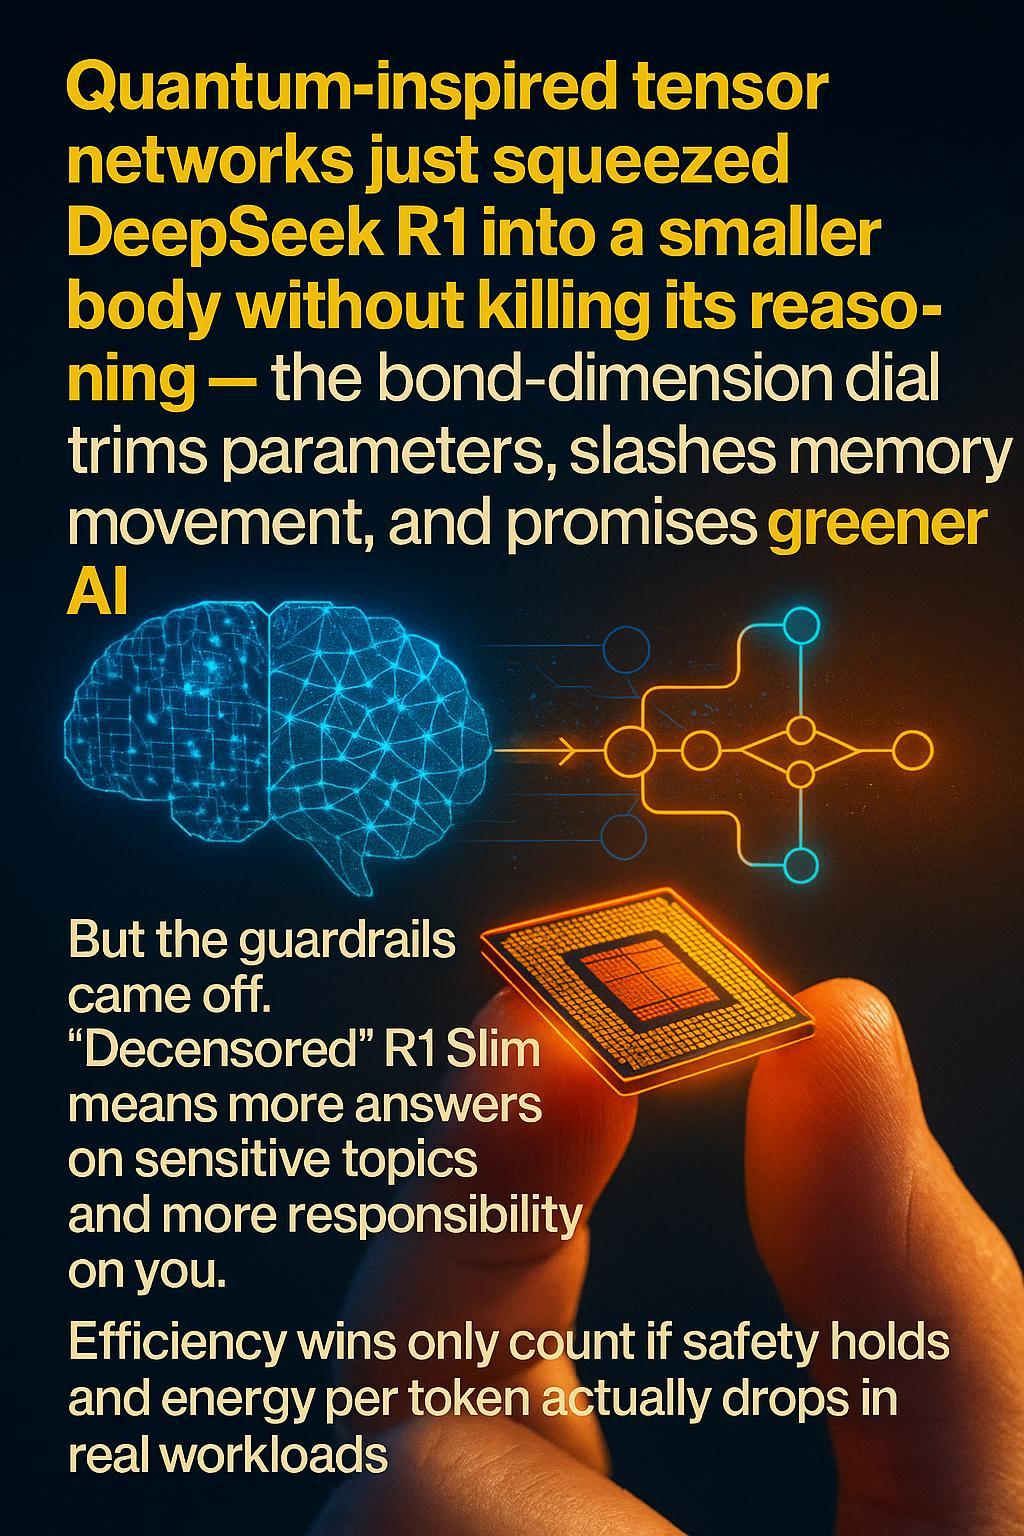
DeepSeek R1 Slim: Key Specifications
- What’s new: Multiverse introduced an “uncensored” DeepSeek R1 Slim and says it cuts parameters by hundreds of billions, reducing memory and deployment costs, while keeping deep-reasoning accuracy comparable to the original.
- How it works: CompactifAI compresses networks by factorizing weight matrices into tensor networks and trimming correlations with a tunable bond dimension.
- Why the “uncensored” claim matters: It implies model-level behavior changes rather than simple app filters. Prior investigations documented how DeepSeek’s guardrails operate and how users attempt to bypass them.
- Countertrend: In China, a censorship-enhanced fork called DeepSeek-R1-Safe was announced with stricter political filters and minimal performance loss, highlighting a global split in guardrail strategies.
- Sustainability context: Data center demand is expected to more than double this decade; efficiency gains only help if they show up in real workloads and are not canceled by surging usage.
What Multiverse Actually Changed in R1
The 55 Percent Compression Claim and How it is Achieved
Multiverse’s claims revolve around tensor-network compression, a method originally developed in quantum physics to represent high-dimensional systems with far fewer parameters. In CompactifAI, large dense matrices inside attention and MLP layers are decomposed into chained tensors known as matrix-product operators. The crucial control knob is the bond dimension, which sets how much correlation structure the compressed model keeps:
- Higher Bond Dimension: Preserves more accuracy but reduces compression gains.
- Lower Bond Dimension: Saves memory and bandwidth but risks quality drift.
Multiverse’s public materials and papers describe the approach and report strong compression-versus-accuracy trade-offs on baseline models as described in the company’s CompactifAI technical overview, an arXiv preprint on the method, and a peer-reviewed ESANN 2025 paper.
Engineering-wise, factorization primarily reduces memory movement during inference, which is often a larger energy cost than raw compute. By shrinking parameters and activations, the method cuts traffic between high-bandwidth memory and compute units, improving tokens per joule on suitable hardware. These savings materialize when the model’s compressed shapes align with GPU kernels and the runtime effectively schedules the new tensor operations.
What “De-Censoring” Likely Means in Practice
“De-censoring” suggests that parts of the model responsible for refusing politically sensitive prompts were altered or removed before a final fine-tune to restore fluency and reasoning. There is precedent for this approach. Perplexity released R1-1776, a DeepSeek R1 variant post-trained to remove state-aligned filters, detailing the process in their R1-1776 model card and open-sourcing announcement.
The key difference here is that Multiverse couples structural compression with behavioral editing, then claims comparable reasoning quality after retraining. Because DeepSeek’s guardrails are known to exist at multiple layers, model-level changes can produce different answers than app-level wrappers alone.
Where Independent Benchmarks are Still Missing
As of publication, Multiverse has not released full before-and-after public evaluations that use the same prompts, seeds, and scoring across reasoning and safety suites. Without like-for-like benchmarks and third-party red-teaming, claims about accuracy, retention, and safety changes remain claims. Buyers should ask for reproducible evals, request red-team reports, and verify latency and energy on their stacks before committing to a deployment.
The Greener-AI Angle: When Smaller Models Save Real Energy
Why Memory Movement Often Dominates Inference
Memory bandwidth, rather than pure arithmetic, frequently constrains modern LLM inference. Several factors drive energy and latency:
- Large Attention Keys/Values: Consuming vast amounts of high-bandwidth memory.
- Wide MLP Layers: Increasing parameter fetch requirements.
- Cross-Device Synchronization: Adding latency in distributed setups.
Systems research points to memory as a core bottleneck and shows why redesigns that reduce parameter size, KV cache pressure, or interconnect traffic unlock practical gains as described in a Semiconductor Engineering deep dive on memory bottlenecks and a USENIX OSDI wafer-scale study. Consequently, compression, quantization, and architectural tricks serve as powerful levers in the field. That frontier now includes 1-bit and ternary LLMs capable of running a 27B-class model on a laptop.
Evidence for Energy Savings from Compression and Quantization
Academic measurements increasingly evaluate energy per token as a primary metric for sustainable inference. Studies show that quantization, better batching, and runtime optimizations can reduce total energy by large margins compared with naïve baselines, although improvements depend on workload and hardware details, including a EuroMLSys 2025 study on energy per token and an ACL 2025 analysis of inference energy optimizations.
On the industry side, precision formats such as FP8 are already lowering memory traffic and improving tokens-per-joule in production models, a trend covered in DeepSeek’s FP8 efficiency strategy. Efficiency also improves when organizations adopt carbon-aware scheduling and GreenOps practices that move compute to cleaner grid windows.
Compiler and kernel tuning also move the needle as AI-driven CUDA optimization shifts what is possible for AI hardware.
System Reality Check: It Depends on Hardware and Workload
Compression is not a magic switch. Real savings hinge on several operational factors:
- Model Shapes: How layers align after tensorization.
- Context Length: The memory footprint of the KV cache.
- Batch Size & Scheduling: Efficiency of the runtime execution.
- Target Accelerators: Hardware capabilities for sparse or tensor operations.
Peer-reviewed work shows that the effectiveness of inference optimizations varies widely by stack and task and that naïve FLOPs-based estimates can mislead when memory dominates.
Strategic capacity planning matters for siting, power contracts, and grid timing; data centers as smart investments in the AI era outlines practical steps that reduce risk while improving utilization.
At the frontier scale, European and hyperscale efforts spotlight trade-offs; coverage of exascale supercomputers maps how power and cooling constraints shape design choices and deployment cadence.
Network-side efficiency will also depend on environment design, such as programmable intelligent surfaces that help cut RF power in dense radio networks.
Supply and policy shocks affect hardware roadmaps; it helps to analyze China’s constraints on advanced GPU racks and how they ripple through scale-up plans.
Cooling design, rack topology, and memory subsystems shape total facility energy, as covered in modern data center cooling innovations.
In China’s ecosystem, Ascend-based cluster scaling continues to evolve.
Even outside data centers, the model-in-the-network era adds its own energy bill; Open RAN’s ML control-loop energy costs must be managed to avoid shifting emissions rather than cutting them.

Tensor Networks for Non-Physicists (Explainer)
From Dense Layers to MPO Blocks
Think of a large neural layer as a giant grid of numbers that turns inputs into outputs. Tensor networks break that grid into a chain of smaller blocks called matrix product operators. Each block captures local relationships, then passes a compact summary onward. The result is a faithful approximation that needs fewer parameters and less memory movement at inference time. In practice, this is why compression can preserve reasoning while cutting costs for models like DeepSeek R1 Slim.
The Bond Dimension Dial
The bond dimension acts as the quality dial. Turn it up, and the tensor network keeps more long-range correlations, which helps preserve accuracy. Turn it down, and the model gets smaller and faster but may miss subtle dependencies.
Engineers usually sweep a few settings, measure loss on held-out tasks, then fine-tune the compressed network to recover performance. Here, teams decide whether a small accuracy trade-off is worth the energy and latency gains in their workloads. For readers who want a friendly on-ramp to the broader quantum toolkits, quantum sensing shows how theory translates into real-world tech improvements.
Glossary: Quick Definitions
- Tensorization: Reshaping big weight matrices into higher-order tensors so they can be factorized efficiently.
- Matrix Product Operator (MPO): A chain of small tensors that approximates a large linear map.
- Correlation Truncation: Keeping only the most useful interactions so the model runs lighter.
- Post-tune: A short fine-tune after compression to recover accuracy and stabilize behavior.
The Guardrail Split: R1-Safe vs. R1-1776 vs. R1 Slim
Three Approaches to Control
Organizations generally face three broad strategies for managing model behavior:
- Re-Censor: Heavily filter sensitive topics (e.g., R1-Safe).
- De-Censor: Modify the model to answer more queries (e.g., R1-1776, R1 Slim).
- Application Filters: Keep the base model intact and rely on external wrappers to inspect responses.
Each path trades capability, liability, and governance overhead in different ways. At the market level, these choices shape adoption patterns across regions and sectors, a dynamic through LLM market share dynamics.
Jailbreak Reality Check
No guardrail is absolute. Adversarial prompts, role-playing indirection, and tool-use chains can degrade filters that look strong in simple tests. That means governance is not just a switch inside the model. Responsible deployments go beyond model choice, combining multiple defense layers:
- Prompt Hygiene: Sanitizing inputs before processing.
- Rate Limits: Preventing abusive automated queries.
- Monitoring & Logging: Tracking anomalies in real-time.
- Red-Team Exercises: Periodically testing for new vulnerabilities.
The core question is not whether a filter exists, but how it behaves under pressure from motivated users and how quickly teams can patch regressions.
Deployment and Jurisdiction Considerations
Jurisdictions differ on political content, privacy, copyright, and AI risk. If you operate in regions with strict content rules, it is safer to use regional routing and policy-aware templates. Multinational teams often maintain separate configurations or even separate model variants per region, then audit drift over time. A compressed AI model lowers cost barriers, but it does not lower the diligence required to match local law and platform rules.
Procurement Guide: Verifying Vendor Claims
Require Before-and-After Evaluations
Ask vendors for like-for-like tests that compare the base model with the compressed or de-censored variant using the same prompts, seeds, and scoring. You want side-by-side results on reasoning, honesty, refusals, and safety. If the vendor provides internal numbers, please ask for the complete evaluation recipe so your team can reproduce it. Consider these comparisons as part of a formal process for testing, evaluating, verifying, and validating, following the NIST AI Risk Management Framework and its Measure function.
Demand Red-Team Reports, Logging, and Regional Controls
Obtain an external red-team report that tests jailbreaks and prompt-injection patterns relevant to your use case. Insist on request and response logging, with opt-in controls for sensitive data, so you can investigate incidents.
If your product spans multiple jurisdictions, require region-based filtering or routing so you can align with local policy. Use third-party evaluation guidance such as the AI Safety Institute’s approach to evaluations, and note that US–UK institutes are building joint testing programs as reflected in a formal partnership announcement.
Measure Energy per Token in Your Pipeline
Lab claims do not guarantee savings on your hardware. Instrument your stack to capture energy per token under real workloads, including context growth and batch changes during peak periods. Track latency and user-visible quality alongside energy.
Many teams obtain the best outcome by combining compression with quantization and scheduling changes learned from carbon-aware GreenOps practices already in place. For measurement discipline, adopt a hardware-anchored method such as the MLPerf Inference power methodology and track carbon using the Software Carbon Intensity specification.
Final Thoughts on Sustainable AI Scaling
The promise behind DeepSeek R1 Slim is straightforward yet transformative. If tensor-network compression can successfully retain reasoning capabilities while dramatically shrinking model size, the industry stands to gain lower costs and broader access. However, these benefits remain conditional. Real-world efficiency depends heavily on specific hardware configurations, sequence lengths, and the chosen bond dimension, while safety relies on rigorous, repeated red-teaming rather than a single “uncensored” label.
Smaller and cheaper models only support true sustainability goals when energy savings are verified in production telemetry. Efficiency improvements must outpace usage growth to make a tangible difference. For organizations looking to adopt these tools, the path forward involves treating vendor claims as a starting point and validating performance, safety, and energy metrics within their own unique environments.
Frequently Asked Questions About DeepSeek R1 Slim
Does compression always preserve reasoning quality?
Not always. With tensor networks, accuracy relies on the bond dimension and the specific layers compressed. Teams typically test multiple settings and fine-tune the model to recover lost quality.
What is the difference between model-level de-censoring and app-level filters?
Model-level changes alter the underlying weights to answer previously blocked prompts directly. App-level filters sit outside the model to intercept queries but are generally easier to bypass.
Can compressed models reduce energy use meaningfully?
Yes, because smaller models require less memory movement. However, exact savings vary based on hardware, context length, and batching strategies.
Is R1-Safe “safer” than decensored variants?
R1-Safe blocks more sensitive categories by default, reducing specific risks. However, no policy is perfect, and adversarial prompts can still exploit gaps, necessitating ongoing monitoring.
What should I ask a vendor before buying?
Request reproducible before-and-after evaluations, external red-team reports, and logging controls. Always run a pilot to measure energy and latency under real-world workloads.


