Mistral has published a trillion-parameter model that anyone can download. Downloading it is the easy part.
On 29 October, Mistral released the weights of Mistral Large 4 on Hugging Face. The model has about one trillion parameters in total, with 49 billion active in its experts for each token produced, or 52 billion including embeddings and output layers. Anyone can download it, inspect it and fine-tune it. Most organizations can also use it commercially under Mistral’s license.
This is a big moment for open AI. Not long ago, models of this class sat behind closed APIs. New releases now arrive almost weekly, and more of them come with their weights attached.
But a download is not a deployment. A model only becomes useful when it runs somewhere, answers requests quickly and stays available. For frontier-scale open models, that “somewhere” is now the real constraint.
What open weights actually give you
Open weights are the trained numbers that make a model work. With them, you no longer depend on one company’s API. You decide where the model runs, who can reach it and how long you keep it.
Mistral’s VP of Science, Pierre Stock, put it plainly when the weights came out. Access “can’t be cut off by definition because the model is open-weighted,” he told TechCrunch.
That control has a price. The weights arrive without servers, networking, monitoring, or an engineer on call. Everything a hosted API quietly handles becomes your job, or the job of whoever you choose to run it.
A trillion parameters still need a home
Mistral Large 4 is a mixture-of-experts model. It holds about one trillion parameters in total, but only about 49 billion are active in its experts for each token it produces, or 52 billion including embeddings and output layers. That makes each answer cheaper to compute than the headline size suggests.
It does not make the model small. Any expert can be called at any moment, so all the weights must sit in fast GPU memory at once. Compute follows the active parameters. Memory follows the total.
Simple arithmetic shows the scale. At 16-bit precision, each parameter takes two bytes, so a trillion parameters need roughly two terabytes for the weights alone. A 4-bit version needs about a quarter of that, around 500 gigabytes. Every conversation then needs its own working memory on top.
A high-end consumer graphics card holds tens of gigabytes. That is enough for impressive things: Intelligent Living recently covered a 34B world model running in real time on a single RTX GPU. A trillion-parameter model is a different scale altogether.
The hardware gap
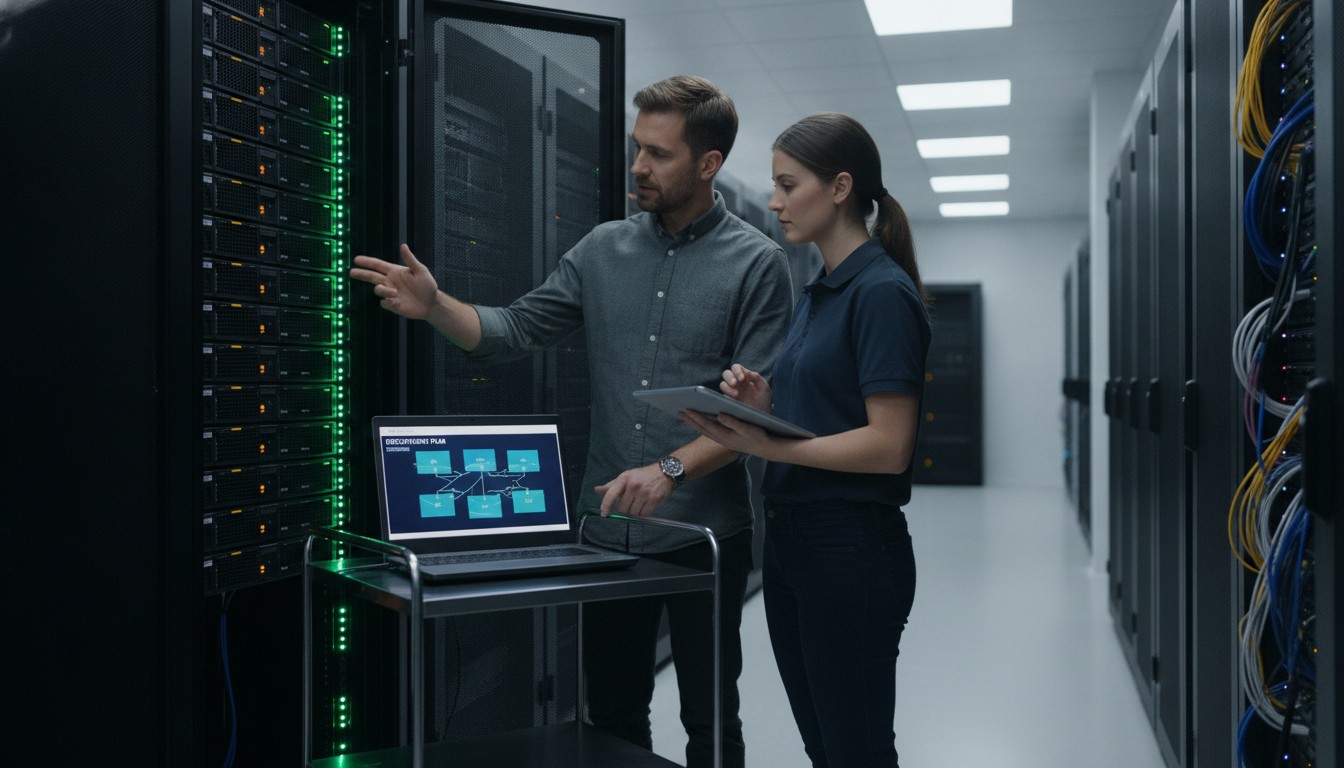
Mistral says a quantized version of Large 4 runs on four NVIDIA B200 or B300 GPUs. That is the entry point, not a gaming PC or a workstation under a desk. In standard server configurations, each B200 carries 180 GB of high-bandwidth memory. Four of them give about 720 GB to hold the model and its working memory.
These GPUs never come alone. They sit in dedicated servers with high-speed links between the chips, specialized power and cooling, and fast storage to load the model. Most organizations have nothing like that in their server room. Buying it means long lead times and a large upfront bill.
Mistral has said smaller distilled versions, including one for laptops, will follow in the coming months. They will widen access. They will not be the same model.
Three ways to run an open model
Once the weights are on your drive, there are three realistic routes.
- Own the hardware. This gives maximum control and no per-request fees. It also means capital spending, procurement, and a team to keep a GPU cluster healthy. It makes sense when usage is high and steady.
- Use a hosted API. Mistral offers Large 4 through its own API and several partner platforms. This is the fastest route. It also hands part of the control back, because every request travels to someone else’s infrastructure under their terms.
- Run it on dedicated rented capacity. A middle path is gaining ground. GPU providers host the model for one customer and expose it as a private endpoint. Teams keep control over where the model runs and who can reach it without buying the cluster. More providers now offer private inference endpoints for open-weight models on Blackwell-class hardware, sometimes on isolated networks that never touch the public internet.
One detail matters here. Mistral’s license is free for most uses, but businesses that offer the model to others as a service need a separate commercial license from Mistral. If a provider hosts Large 4 for you, ask how they handle that.
Five questions before you choose
- How much memory does your version need? Check the precision (16-bit, 8-bit, or 4-bit) and the context length you plan to use.
- Who operates it? Someone has to update drivers, watch performance, and handle failures at three in the morning.
- Where does it run? Know the country, the facility, and who has administrative access.
- How will usage grow? A pilot and a production service have very different load patterns and very different bills.
- What does the license allow? This matters most if you plan to serve the model to your own customers.
The bottleneck has moved
For years, the big question in AI was who had access to the best models. Open weights are answering it. The new question is who can run them well.
The winners of the next phase may not be the teams with the best model. They may be the teams that found the right place to run it.


