
Google DeepMind recently unveiled a breakthrough in digital strategy by training the AlphaEvolve coding agent to rewrite the very foundations of game theory algorithms. This system uses a large language model to evolve core solvers, producing new versions that are significantly harder for opponents to beat.
Instead of just following human-written rules, the AI is now capable of redesigning the logical frameworks it uses to make decisions, especially in complex environments where hidden information is the norm. Moving toward algorithmic evolution represents a major leap in strategic AI development that goes beyond simple automation.
By treating algorithm code like a living organism that can evolve, researchers have discovered new ways to handle uncertainty in settings where “nobody sees the whole board.” Moving beyond simple theory, this is a practical step toward building machines that can navigate high-stakes scenarios—like cybersecurity or market trading—with unprecedented precision and resilience.

The AlphaEvolve Breakthrough: Automating Game Theory Algorithm Design
DeepMind Research: LLMs Rewriting Multi-Agent Game Solvers
A team of DeepMind experts recently shared a study on a new LLM-backed pipeline. This system can propose, test, and refine code edits for multi-agent solvers, creating new algorithm variants that beat human-designed baselines. This discovery debuted in a recent DeepMind research paper before gaining mainstream traction through reporting in early April.
The most striking part of this discovery is how direct the pipeline is.
The AlphaEvolve system is not asked to “be clever” in an abstract way. Instead, it is pushed to make concrete code changes and run those changes against games that score strategic quality. The pipeline only keeps the versions that improve under that scoring.
Snapshot: Core Highlights of the AlphaEvolve Strategy Upgrade
Understanding the scale of this breakthrough requires looking at the specific mechanics of the upgrade. Here is a quick snapshot of how AlphaEvolve shifts the game theory landscape:
- The Process: This automated pipeline uses the AlphaEvolve coding agent to treat software like a mutable genome, using an LLM to propose and score the best candidates.
- Targeting Complexity: The research team focused on two specific algorithm families: counterfactual regret minimization (CFR) and policy space response oracles (PSRO). These were chosen because they are the ‘heavy lifters’ when it comes to solving games where players have hidden cards or secrets.
- Named Variants: The study reports solver variants such as VAD-CFR and SHOR-PSRO for improved benchmark performance under its evaluation setup.
- Metric: Performance was quantified with an exploitability best-response score, where lower values generally mean an opponent can gain less by deviating to a stronger response.
- Testbed: Experiments were run in benchmark suites compatible with the OpenSpiel framework for reproducible game evaluations.

Inside the AlphaEvolve Loop: Code Edits, Benchmarks, and Measurable Wins
Digital Evolution: The Four-Step Loop for Improving Solver Code
AlphaEvolve relies on a rigorous and repeatable process to sharpen digital strategies. To make sure only the toughest code survives, the system follows a tight four-step loop:
- Baseline Selection: The process starts with a working game theory solver as the foundation.
- Code Mutation: A large language model proposes specific, focused edits to the existing code.
- Strategic Scoring: Each new variant is tested against a diverse training set of games.
- Selective Evolution: Variants that improve the performance metric are kept for further refinement in future generations.
By repeating this cycle over and over, the AI constantly discovers more effective ways to play. Keeping only the top-performing versions results in algorithms that are far more resilient than anything built by hand. Focusing on evaluator gates echoes the FunSearch evaluator loop, where candidate programs have to prove themselves under tests instead of persuasive phrasing.
DeepMind’s AlphaEvolve white paper frames this pipeline as a smart engineering pattern. It uses a strong AI model to propose code ideas, then relies on automated tests to prove which ones actually work. In plain terms, the system is not asked to sound convincing. It is forced to run, score, and survive.
Revisiting the Classics: Evolving CFR and PSRO Algorithms
Counterfactual Regret Minimization (CFR)
CFR acts as the primary engine for solving games where players hold private information. It keeps a running tally of regrets—essentially calculating how much better a different decision would have been in hindsight—to nudge strategies toward moves that are much harder to exploit. The foundational research explains how regret accounting works in settings like digital poker where players hide their cards.
Practical applications of this logic appear whenever someone tries to make a smart choice while flying partially blind. While the math behind these solvers is complex, the logic shows up in everyday life. You might benefit from these strategic tools in common situations like:
- Used-Car Bidding: Negotiating a price when you don’t have the full maintenance history.
- Lease Negotiations: Signing a contract that might have hidden or complex clauses.
- Blind Auctions: Deciding on a bid amount without knowing what others are willing to pay.
Each of these scenarios carries the same basic challenge: the best move depends on information that is hidden from view. CFR-style logic is built to handle these lopsided moments with precision. CFR-style algorithms also include fast-tracked versions used in high-level poker research, such as CFR+. Recent progress in enhancing long-memory reasoning for AI models aims to improve what systems can retain while making complex decisions, but this paper targets the decision rules underneath.
Policy Space Response Oracles (PSRO)
Think of PSRO as a rotating scrimmage. Each new policy is trained to handle a moving blend of opponents rather than a single frozen rival. This setup helps the system discover strengths and weaknesses that only show up when different strategies collide. In this study, DeepMind’s evolved PSRO variant adjusts how the population is mixed during training and evaluation, aiming for steadier reductions in exploitability rather than brittle wins against a narrow set of opponents. The paper’s SHOR-PSRO meta-solver details describe the kind of smoothing and scheduling tweaks the search discovered.

Measuring Success: Why Lower Exploitability and Benchmarks Prove Strategic Growth
Defining Exploitability: The Numerical Standard for Algorithmic Strength
Proving that an algorithm works requires a standardized scoreboard. In this study, lower exploitability scores on benchmark tasks show real progress because they are designed to be reproducible within established frameworks. Because exploitability is a numerical objective, it provides clear guardrails against vague comparisons. This style of measurement has now become the default standard in game research, and the OpenSpiel paper’s discussion of evaluation metrics helps explain why.
In simple terms, exploitability asks one basic question: if an opponent plays their best against you, how much can they win? Lower numbers generally mean fewer obvious holes.
The Role of Benchmarks: Mapping Strategy Across Standardized Test Sets
The solver did not merely look smarter. It scored better by a defined metric. That matters, because it forces claims to pass through repeatable tests rather than vibes.
Benchmarks act as a limited mirror, measuring specific behaviors only on selected games and under narrow conditions. Transfer to messy real-world settings is plausible where the strategic structure aligns, but it is not automatic, and it is rarely uniform.
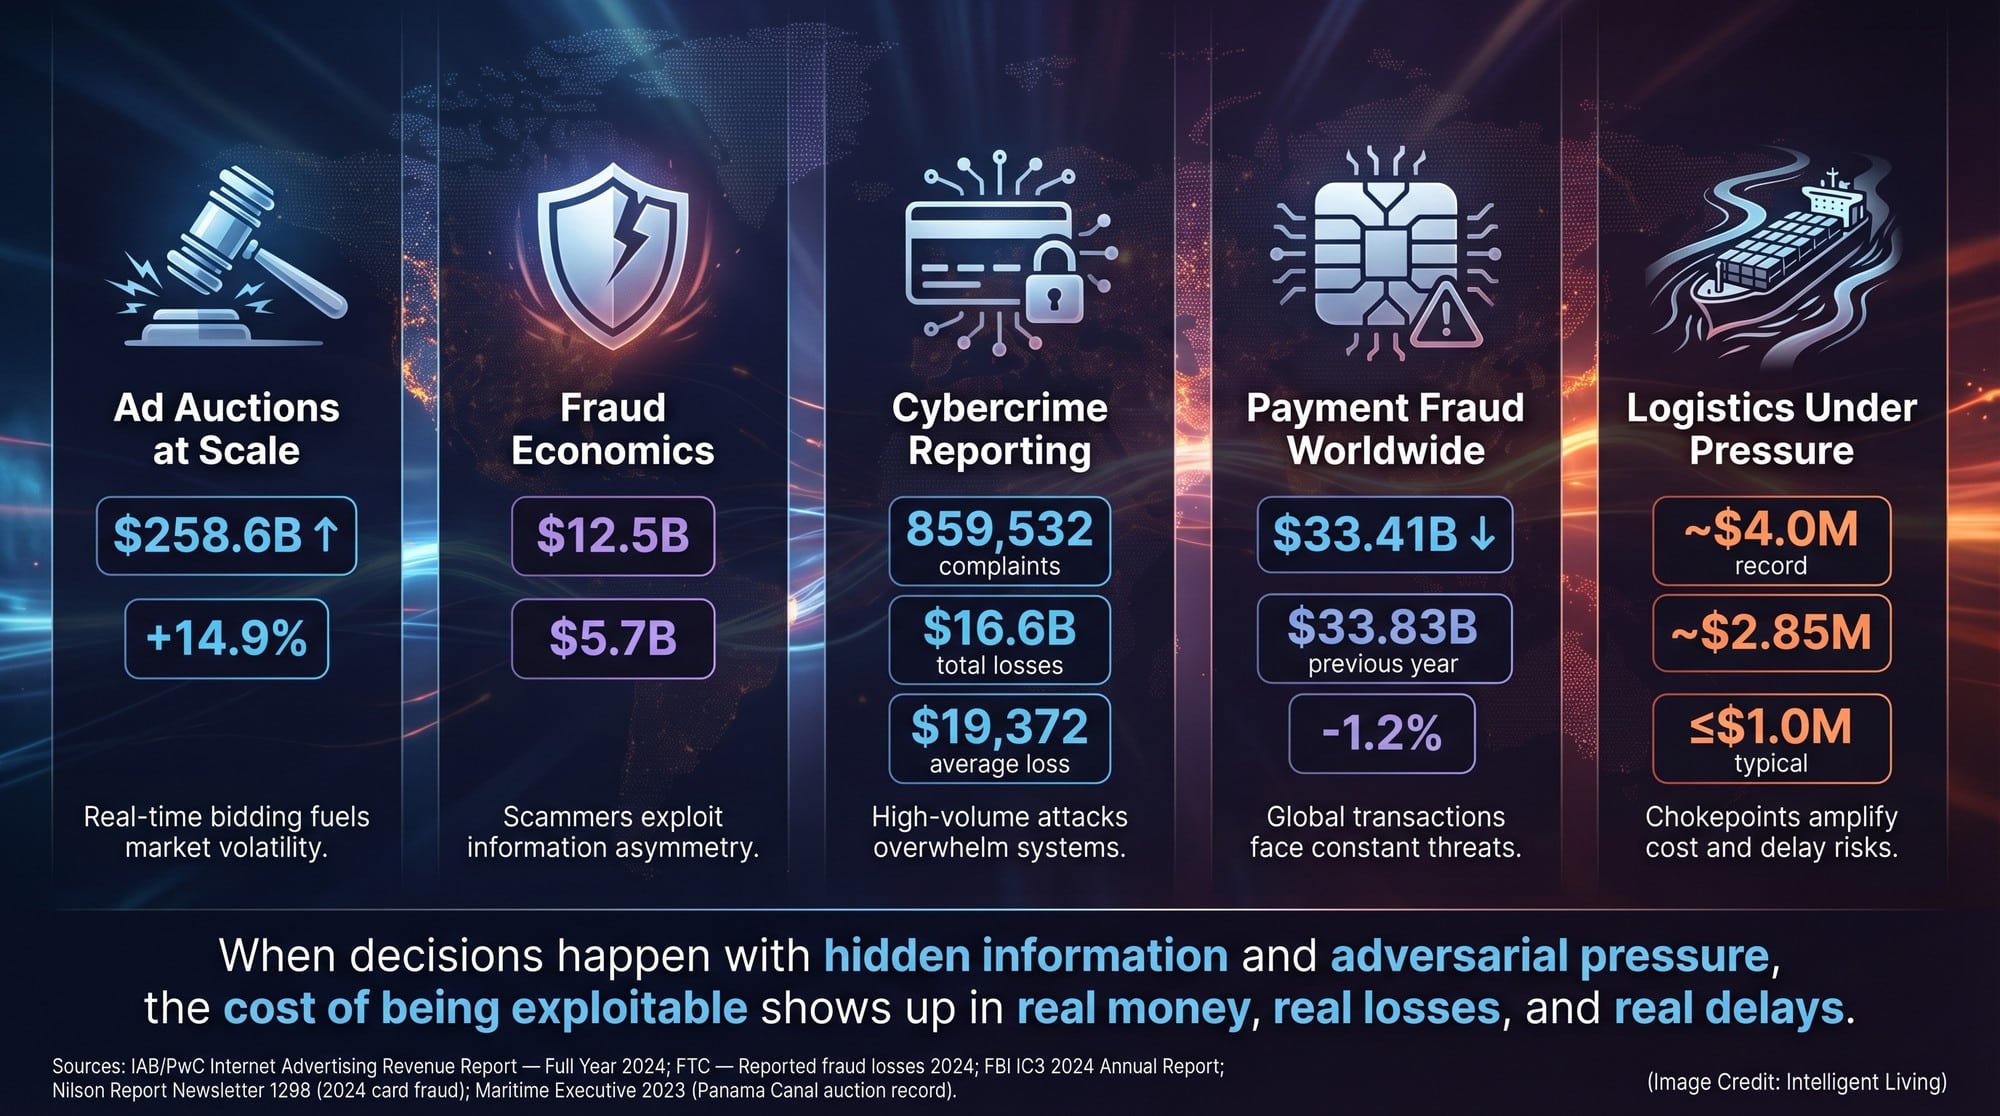
Strategic AI Pathways: Solving High-Stakes Problems Under Uncertainty
Industry Impact: Where Evolved Strategic AI Solves Real Problems
Discovering more resilient solvers is a major win for everyone, as so many real-world systems operate like games with hidden rules. The potential for these solvers to change industries is clear when you look at how strategic logic applies to modern problems. Several areas where this AI could make a real difference include:
- Ad Auctions and Bidding Systems: auction timing, location targeting, and budget pacing turn bidding into a strategic game, and auction optimization in Google Ads is one place that pressure shows up in plain sight.
- Cybersecurity Attacker-Defender Models: defenders rarely know intent, tooling, or timing, so strengthening adaptive cybersecurity for small businesses increasingly centers on playbooks that evolve rather than staying fixed.
- Fraud Detection and Adaptive Abuse: when attackers probe and pivot, AI-powered fraud prevention tends to lean on continuous pattern updating instead of fixed rules that age overnight.
- Automated Negotiation Agents: hidden preferences and sequential offers create poker-style uncertainty, and overcoming the challenges of automated negotiation shows that the hard part is making concessions under pressure.
- Market Microstructure and Strategic Trading: partial observability and adversarial response matter when timing becomes part of the game, and Panama Canal auction slots show how quickly queue position can turn into a bidding strategy under pressure.
These pathways serve as a roadmap for how stronger solvers can tackle real-world tasks. While this research is still early, it opens up new possibilities for designing strategic AI that can handle the messiest environments.
Future Outlook: Why Automated Evaluators Drive Algorithm Discovery
As these solvers move from research labs to real-world applications, the way we build them is also changing. Pairing LLM proposals with evaluator scoring has quickly become the preferred method for making new discoveries. The FunSearch program search paper showed a similar loop can unearth mathematical results by forcing candidates through a strict evaluator rather than trusting fluent text.
Looking ahead, several factors will decide how much we can trust these evolved systems:
- Evaluator Governance: Who manages the tests that pick the winners, and how do we audit their design?
- Agentic Shifts: How tools and automated tests become as important as the AI chat itself.
- Goal Alignment: Making sure that AI agent societies don’t slip into power games by setting better performance metrics today.
The Impact of Evolved Solvers: A New Era for Automated Strategic AI
The success of the AlphaEvolve project highlights a pivotal change in how we build intelligent systems. We are moving into an era where machines don’t just solve problems; they suggest and validate improvements to the rules that other machines follow. While this doesn’t replace the need for human oversight, it drastically reduces the manual labor required to design complex AI solvers. By automating the trial-and-error process of coding, we can accelerate the pace of discovery in fields that rely on calculating perfect moves under pressure.
The true value of these systems will be proven in messy, real-world environments. As we integrate these tools into our digital world, the focus must shift toward making the logic behind every machine-made choice clear and easy to audit. Ensuring that we understand the ‘why’ behind these machine-made choices is essential for building trust in a world where autonomous systems are increasingly responsible for our most sensitive strategic decisions.
Frequently Asked Questions: Understanding AlphaEvolve and Game Theory
What exactly is AlphaEvolve?
AlphaEvolve is an AI-driven coding tool from Google DeepMind that uses evolutionary search to improve computer algorithms. It works by suggesting code changes, testing them against a scoreboard, and keeping only the most effective versions.
How does this improve game theory solvers?
The system automates the design of solvers like VAD-CFR and SHOR-PSRO. By evolving the code itself rather than just tuning settings, it discovers non-intuitive strategies that human experts might never consider.
What does ‘lower exploitability’ actually mean?
In strategy games, exploitability is a metric that shows how much an opponent can gain by taking advantage of your weaknesses. A lower exploitability score means your strategy is more ‘airtight’ and harder to beat.
Can AlphaEvolve help with real-world problems?
Yes. The principles behind this research apply to any scenario with hidden information, such as defending against cyberattacks, optimizing ad auctions, or negotiating complex business contracts.
Is the AI writing its own code from scratch?
Not exactly. It starts with a human-written baseline and uses an evolutionary loop to ‘mutate’ and refine the logic. It acts more like a high-speed collaborator that explores thousands of variations to find the best one.


